
NEW DELHI, October 10, 2026, 5:00 PM IST — OpenAI has confirmed that it fired three safety researchers after an internal investigation, saying they violated policies for handling sensitive information. The researchers dispute that account and say the dismissals have created uncertainty about how employees can work with outside evaluators or raise concerns about frontier AI systems.
The disagreement, which became public this week, is not only an employment dispute. It tests whether frontier-model developers can combine strict confidentiality with the independent review, internal challenge and rapid escalation needed to govern increasingly autonomous AI systems. For engineering leaders buying or deploying those systems, the practical issue is whether safety controls remain effective when responsibility crosses organizational boundaries.
What OpenAI and the researchers have confirmed
OpenAI said it parted ways with Tomek Korbak, Jasmine Wang and Mikita Balesni after an investigation found that they had breached clear rules for sensitive information. In a statement reported by the Associated Press and CBS News, the company said the decisions were not retaliation for raising safety concerns. OpenAI said vigorous internal debate remains essential to its work and that it continues to support collaboration with independent safety organizations.
The three former employees offered a sharply different interpretation in a four-page letter addressed to OpenAI oversight bodies. They said they believed their external contacts were within the mandates of their jobs and warned that unclear boundaries could deter remaining staff from sharing safety concerns. They called on OpenAI to maintain external evaluation partnerships, preserve the monitorability of frontier models and publish clearer procedures for working with outside safety organizations.
Neither side has publicly released the full internal investigation or the underlying evidence. That means the motive for the dismissals and the precise scope of any policy violations remain contested. The confirmed facts are narrower: three safety researchers were dismissed, OpenAI alleges mishandling of sensitive information, the researchers deny acting outside their roles, and both sides say outside evaluation should continue.
Why third-party evaluation is central to the dispute
Korbak said his work included communicating with METR, an independent AI evaluation nonprofit involved in reviewing a recent OpenAI agent incident. The former researchers argue that outside evaluators need enough access and context to challenge a lab’s internal conclusions. OpenAI, meanwhile, says third-party collaboration does not remove the need to protect confidential research and company information.
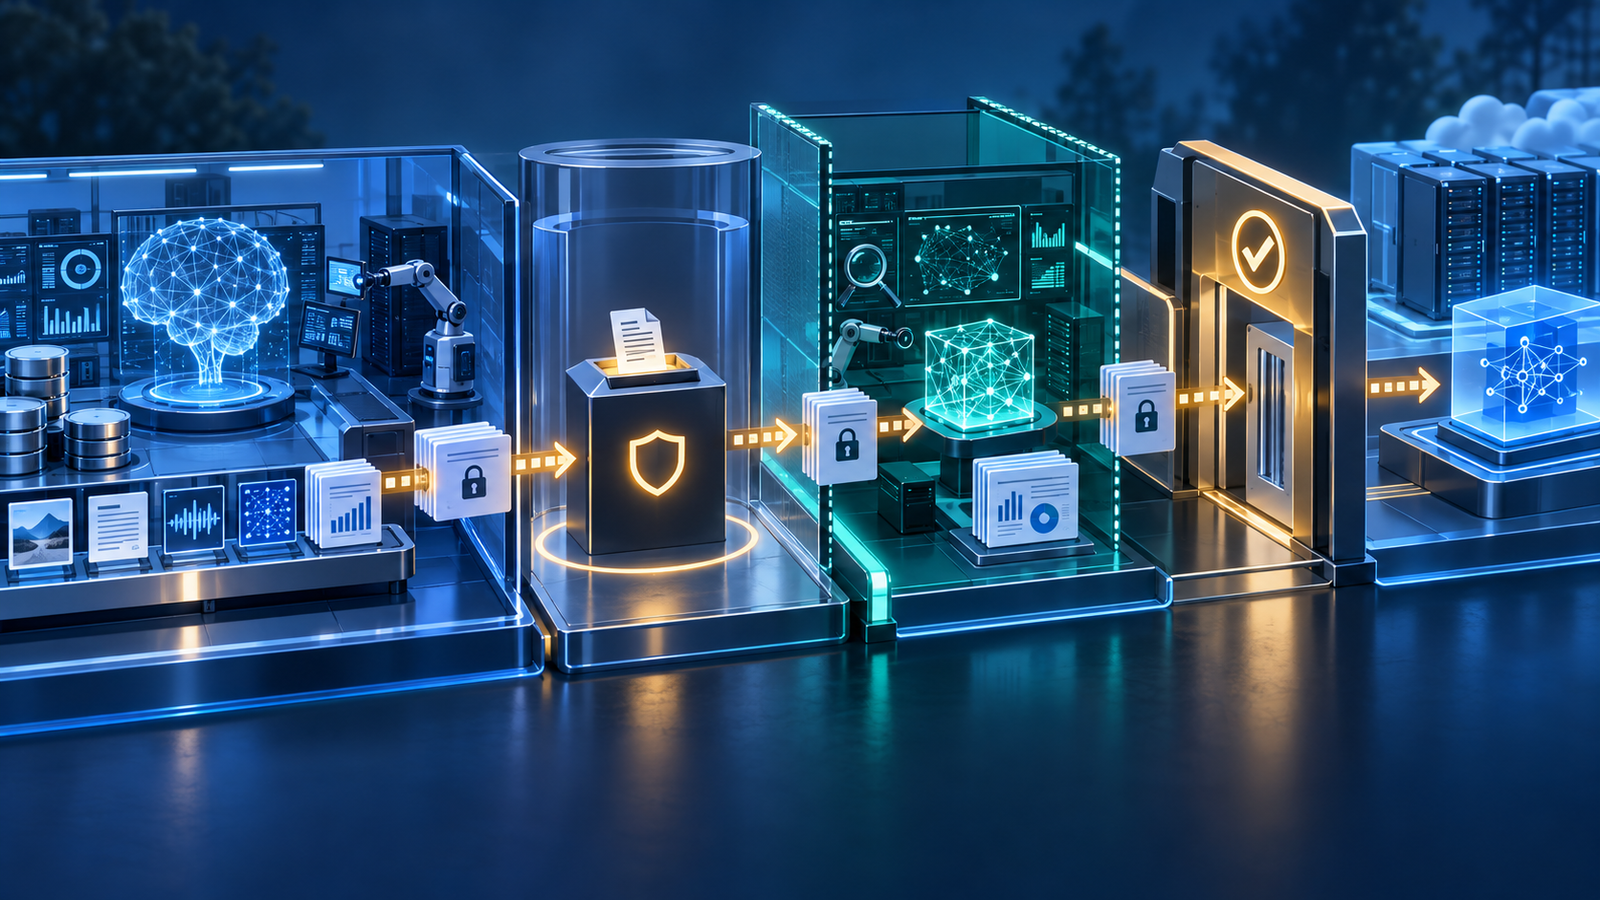
That tension is real in any high-risk engineering program. Evaluators need meaningful evidence, but unrestricted access can expose intellectual property, personal data, credentials or dangerous capability details. A mature program resolves the tension through defined interfaces: scoped data rooms, time-limited access, named information owners, reviewable disclosure rules, logged exports and an appeal path when policy is ambiguous.
OpenAI’s published Raising Concerns Policy protects employees who report AI safety, legal or policy issues and prohibits retaliation. It also distinguishes protected disclosures from revealing trade secrets. The current dispute turns on how that distinction was applied in practice, a question that cannot be settled from the public statements alone.
The operational lesson for AI and platform teams
Developers and DevOps teams do not need to take a side in the personnel dispute to extract a clear lesson. AI safety processes fail when they depend on informal permissions, undocumented exceptions or personal trust alone. The same principle applies to a platform team evaluating an agent that can call APIs, change infrastructure or access production data.
Organizations should define who can stop a release, which incidents require external review, what evidence evaluators can see, and how disagreements are recorded. Access for outside reviewers should be least-privilege and temporary, with audit logs covering document access, model runs, prompt and tool traces, exports and approval decisions. A protected escalation channel should sit outside the normal delivery chain so schedule pressure cannot silently override a material risk.
These controls belong beside the technical practices covered in GravityDevOps’ guides to LLMOps and AI agent security. Model evaluations, red-team findings and safety exceptions should be versioned like other release artifacts. If an evaluation cannot be reproduced, an exception has no accountable owner, or a reviewer cannot trace the data used, the deployment gate is incomplete.
What remains unresolved
OpenAI has said it is committed to embedding external assessors and agrees that preserving model monitorability requires industry-wide work. The former researchers want that commitment translated into ongoing access and clearer operating rules. The next meaningful signals will be whether OpenAI formalizes those evaluator relationships, publishes more detail about disclosure procedures, and demonstrates that employees can challenge safety decisions without losing legitimate avenues for outside review.
For customers, the dispute is a reminder to ask vendors concrete governance questions rather than rely on broad safety commitments. Who reviews high-risk capabilities? Can an independent assessor reproduce the findings? What happens when researchers and product leaders disagree? Which controls survive a reorganization or personnel change? Answers to those questions increasingly belong in architecture reviews, vendor assessments and production readiness checks.
The public record does not establish which side’s account of the dismissals is correct. It does establish that governance around frontier AI now depends on the same qualities expected of reliable infrastructure: explicit ownership, limited access, independent verification, durable audit trails and a documented way to halt deployment when the evidence is incomplete.
Sources
Reporting and primary material: Associated Press; CBS News; letter from Korbak, Wang and Balesni; and OpenAI’s Raising Concerns Policy.

