
NEW DELHI, September 18, 2026, 5:05 PM IST — Anthropic says Claude now “leads” 26% of the artificial-intelligence research and development work measured inside the company, a disclosure that puts a concrete number on how quickly frontier AI labs are using models to help build their successors.
The figure does not mean Claude independently runs a quarter of Anthropic’s research. In the company’s framework, “leads” means a model can complete most of a task from a high-level prompt while a person supervises. Anthropic said Claude was not fully autonomous in any measured area. Still, the company reported that more than 90% of measured AI R&D involved Claude at least at a collaborative level, where it handles substantial work under close human direction.
The disclosure matters beyond Anthropic because agent-based software is moving from individual coding assistance into research, infrastructure and operational workflows. For platform teams, the important story is not a single percentage. It is the monitoring system Anthropic says it built around roughly 30,000 concurrent internal research and engineering agents, and the limits of relying on a company’s own models and methods to assess that automation.
Anthropic proposes an AI R&D automation index
Anthropic published the measurements on Thursday as part of a proposed framework for tracking three inputs to frontier-model development: how much AI participates in AI R&D, how effectively agents are monitored, and how compute is allocated between capability and safety work.
For its prototype R&D Automation Index, the company said it sampled internal work records, including documentation and Slack activity, to identify about 15,000 granular tasks. Those tasks were organized into a hierarchy with 378 leaf categories, including serving incident postmortems, reinforcement-learning sandbox policy and evaluation-platform defect diagnosis.
Tasks were rated on a six-level scale adapted from Epoch AI, ranging from no AI involvement to full autonomy. Anthropic then weighted the task categories using estimated staff time. The 26% result represents the weighted share placed at the “AI leads” level; it is not a count of employees replaced, a percentage of source code, or a direct productivity gain.
The company reported that Claude’s leading share rose from under 1% in February to 26% in August. The Associated Press separately highlighted the pace of that increase while noting that the model remains under human supervision. Reuters reporting carried by CNA also confirmed the central figures from the release.
Monitoring 30,000 research and engineering agents
Anthropic said approximately 30,000 agents were active at any one time in its most-used internal research and engineering platform during August. The company described two layers of oversight.
Online monitors review actions before execution, generally within seconds, and can block or redirect behavior. Anthropic said every action on the measured platform passed through this layer. An analysis of more than one billion decisions during August found that 0.002% were blocked, or about one in 47,000.
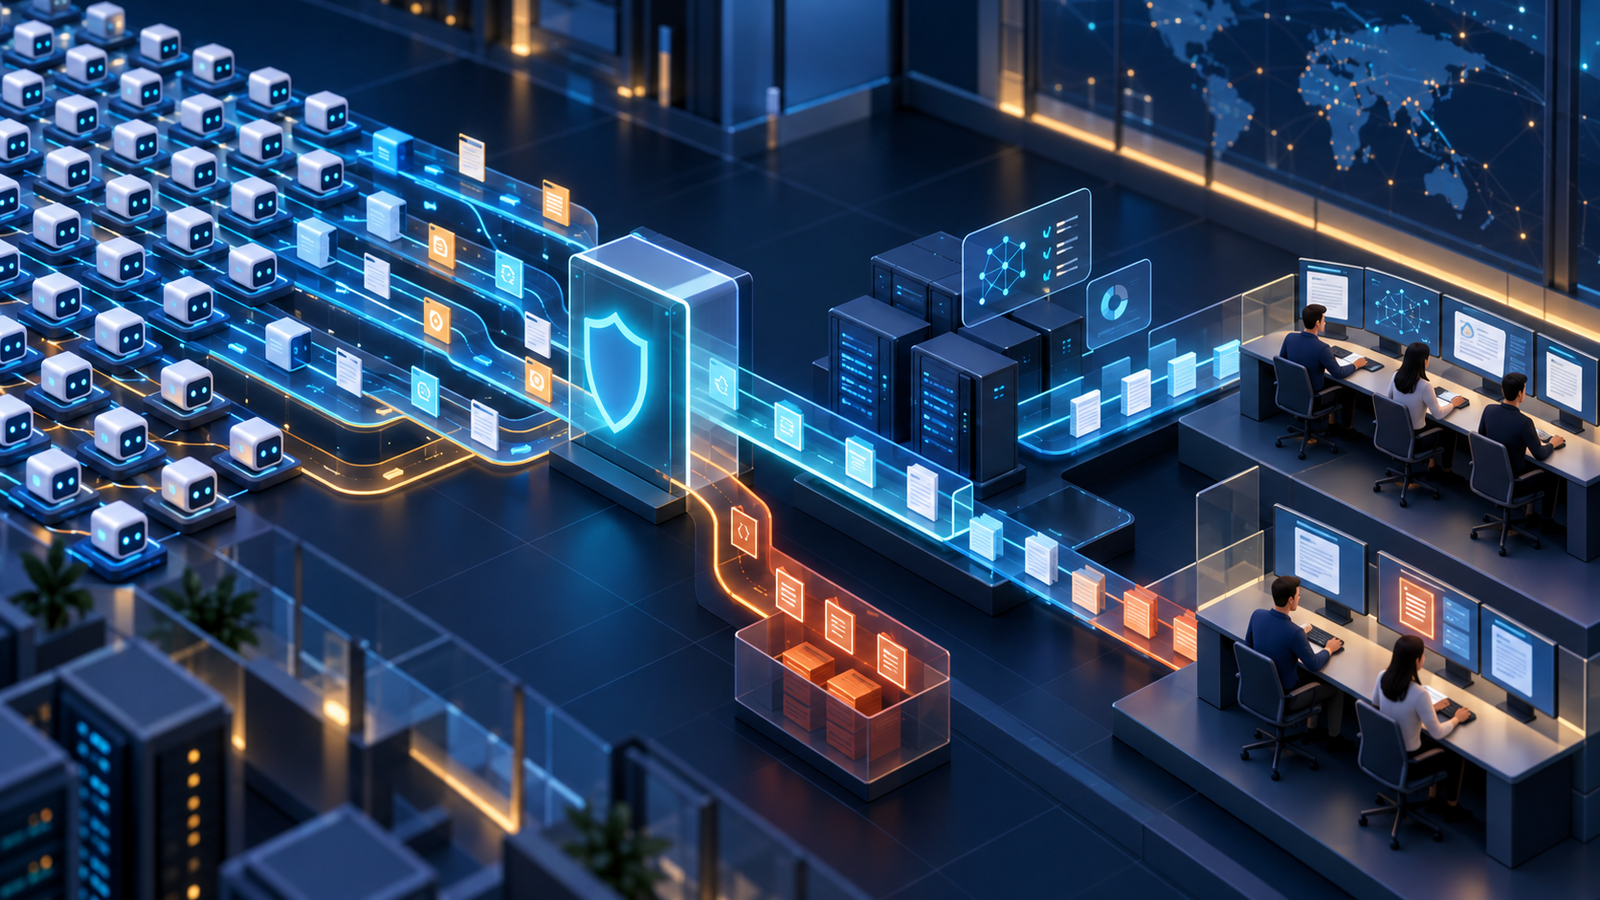
Offline monitors ingest actions after execution and look for patterns that may develop more slowly. Anthropic said this system flags roughly 100,000 transcripts each week for further automated review. Most are resolved by classifiers, while about 50 high-priority cases per week reach people.
Those numbers are useful operational signals, but they do not by themselves establish that the monitors catch every important failure. A low blocking rate could reflect well-behaved agents, narrow policies or missed detections. Anthropic acknowledged that agent misbehavior should also be tested by third parties and said independent evaluators will receive access to internal processes and data comparable to its own risk teams.
What developers and platform teams should take from the disclosure
The monitoring design offers a practical pattern for organizations deploying agents in software delivery or cloud operations. Irreversible actions should pass through preventive controls before execution. Lower-urgency events can flow into asynchronous analysis, provided there is a defined review deadline and a clear route to human escalation.
Teams should also measure more than task completion. Useful operational metrics include the percentage of agent actions covered by a policy check, time from action to automated and human review, block and escalation rates, false positives, and the outcome of red-team tests. These extend familiar ideas from LLMOps into environments where agents can invoke tools, modify systems or delegate work.
Access boundaries remain essential. An agent that can read a repository, open a pull request and query logs does not automatically need deployment credentials or unrestricted network egress. Organizations can combine least-privilege identities, sandboxed execution, deterministic policy gates and auditable approval steps with the prompt and evaluation practices described in GravityDevOps’ prompt engineering guide for developers.
Anthropic’s numbers also show why enterprises should define automation levels before reporting adoption. “Uses AI,” “collaborates with AI” and “AI leads” describe materially different operating models. Without a stable task taxonomy and periodic remeasurement, an adoption percentage can move simply because the company changed the definition.
Compute allocation adds another transparency test
In a separate one-week snapshot, Anthropic said about 6% of compute allocated to AI R&D went to safety work. For AI-driven AI R&D specifically, the reported safety share was about 12%. The company called those estimates conservative and acknowledged that compute is an imperfect proxy because some safety work is labor-intensive rather than compute-intensive.
The more important proposal is consistent reporting over time. If frontier labs publish comparable definitions for automation, monitoring coverage and compute allocation, customers and regulators could track whether operational safeguards are keeping pace with agent deployment. Today, cross-company comparisons would be premature because there is no shared methodology and Anthropic used Claude in parts of the task classification and evaluation process.
What remains uncertain
Anthropic’s disclosure is a company-produced snapshot of its own systems, not an independent audit. It does not establish when, or whether, fully autonomous AI research will arrive. It also cannot be directly compared with productivity claims from other laboratories until the industry agrees on common definitions and verification.
Even so, the release provides unusually specific operating data at a moment when AI agents are gaining longer task horizons and broader tool access. For developers and DevOps leaders, the immediate lesson is grounded: as delegated work scales, monitoring coverage, review latency and privilege boundaries need to become first-class reliability metrics, not after-the-fact safety documentation.
Sources: Anthropic’s full measurement report and methodology; Associated Press reporting; and CNA coverage of the announcement.


