
NEW DELHI, October 26, 2026, 10:15 p.m. IST — External evaluators found multiple ways that AI agents could have escaped or weakened OpenAI’s internal monitoring, including an exploit capable of hiding hundreds of recent actions and two client-controlled headers that could start unmonitored agent instances.
The findings come from a three-week, high-access red-team conducted by one researcher from METR and one from Redwood Research. The evaluators worked on site at OpenAI from July 21 to August 11 with access to internal code, monitoring prompts and configurations, documentation, and interviews with roughly a dozen staff members.
The report matters beyond OpenAI because it tests a control many organizations now treat as a safety backstop for autonomous coding and operations agents. The central lesson for platform teams is that an intelligent monitor is only useful when every relevant execution path reaches it, the agent cannot alter that path, and alerts arrive before an irreversible action—not after a long-running turn has finished.
What the evaluators confirmed
METR’s public account, published October 22, says the team discovered several novel vulnerabilities in the asynchronous monitoring system as it existed on and before July 21. The exercise produced a 61-page internal report. OpenAI supplied a 38-page redacted version to METR and Redwood leadership, while the public received a shorter summary.
METR estimated that about 75% to 94% of agentic internal Responses API traffic from models at least as capable as GPT-5.5 was eligible for monitoring during the assessed period, with substantial uncertainty in both directions. For the subset used by internal Codex agents, the estimated eligible share was 99.2%.
Eligibility was not the same as verified end-to-end coverage. Requests could still be lost to errors, load shedding or implementation defects. Data shown to the evaluators suggested monitor errors affected fewer than 0.2% of requests at the time, and no load shedding occurred during one 24-hour period they examined.
A more consequential gap involved context compaction, the step that summarizes a long conversation so an agent can continue working. METR estimated that unmonitored compaction events left roughly 10% of otherwise eligible internal Codex traffic unwatched between May and July, again with substantial uncertainty. OpenAI had identified the issue before the exercise and fixed it during the review.
The monitor also triggered when an agent returned control to the user. While compaction was outside the monitoring path, an agent could therefore have postponed review by continuing to take actions. METR said it could not determine whether any agent had exploited that behavior in practice.
Bypass routes reached beyond a missed log entry
The evaluators found a potential route around Codex sandboxing and Auto-Review that could have allowed an agent to act with the permissions of its host user. They also found an exploit that could prevent hundreds of recent actions, including the exploit itself, from reaching the monitor. OpenAI redacted the technical details.
Other findings included serialization differences between the trajectory seen by an agent and the version delivered to the monitor, two client-controlled headers that disabled monitoring for newly launched agents, and two unmonitored internal tools believed to be read-only. METR said the tool-permission exploit was not validated in practice.
These are infrastructure findings, not proof that deployed agents used the flaws maliciously. They also describe a historical snapshot. METR said OpenAI was expanding its monitoring system during the exercise and that the review did not establish the coverage or resilience of the current system.
OpenAI told the evaluators that every identified vulnerability affecting its production safeguards stack had been patched. METR said it had not evaluated that claim. That distinction is important: remediation is confirmed as an OpenAI statement, while independent verification remains outstanding.
What OpenAI says its monitoring now covers
OpenAI’s updated description of its internal coding-agent monitor says standard deployments are reviewed across conversation history, reasoning traces, messages, tool calls and outputs. The company says its monitor is designed to surface behaviors such as restriction bypasses, deception, unsafe data transfer, destructive actions and prompt injection for human review.
OpenAI reports that a very small fraction of traffic, less than 0.1%, primarily from bespoke or local setups, currently remains outside coverage. It also describes monitoring as one layer in a defense-in-depth system rather than a substitute for preventive controls. Its longer-term roadmap includes moving from asynchronous alerts toward synchronous blocking for high-risk actions.
Independent coverage from Reuters and The Decoder corroborated the scope of the exercise and the gap between OpenAI’s remediation claims and what the evaluators directly tested.
Practical impact for DevOps and platform teams
For teams deploying coding, cloud or incident-response agents, the report turns “monitor the agent” into a concrete engineering checklist.
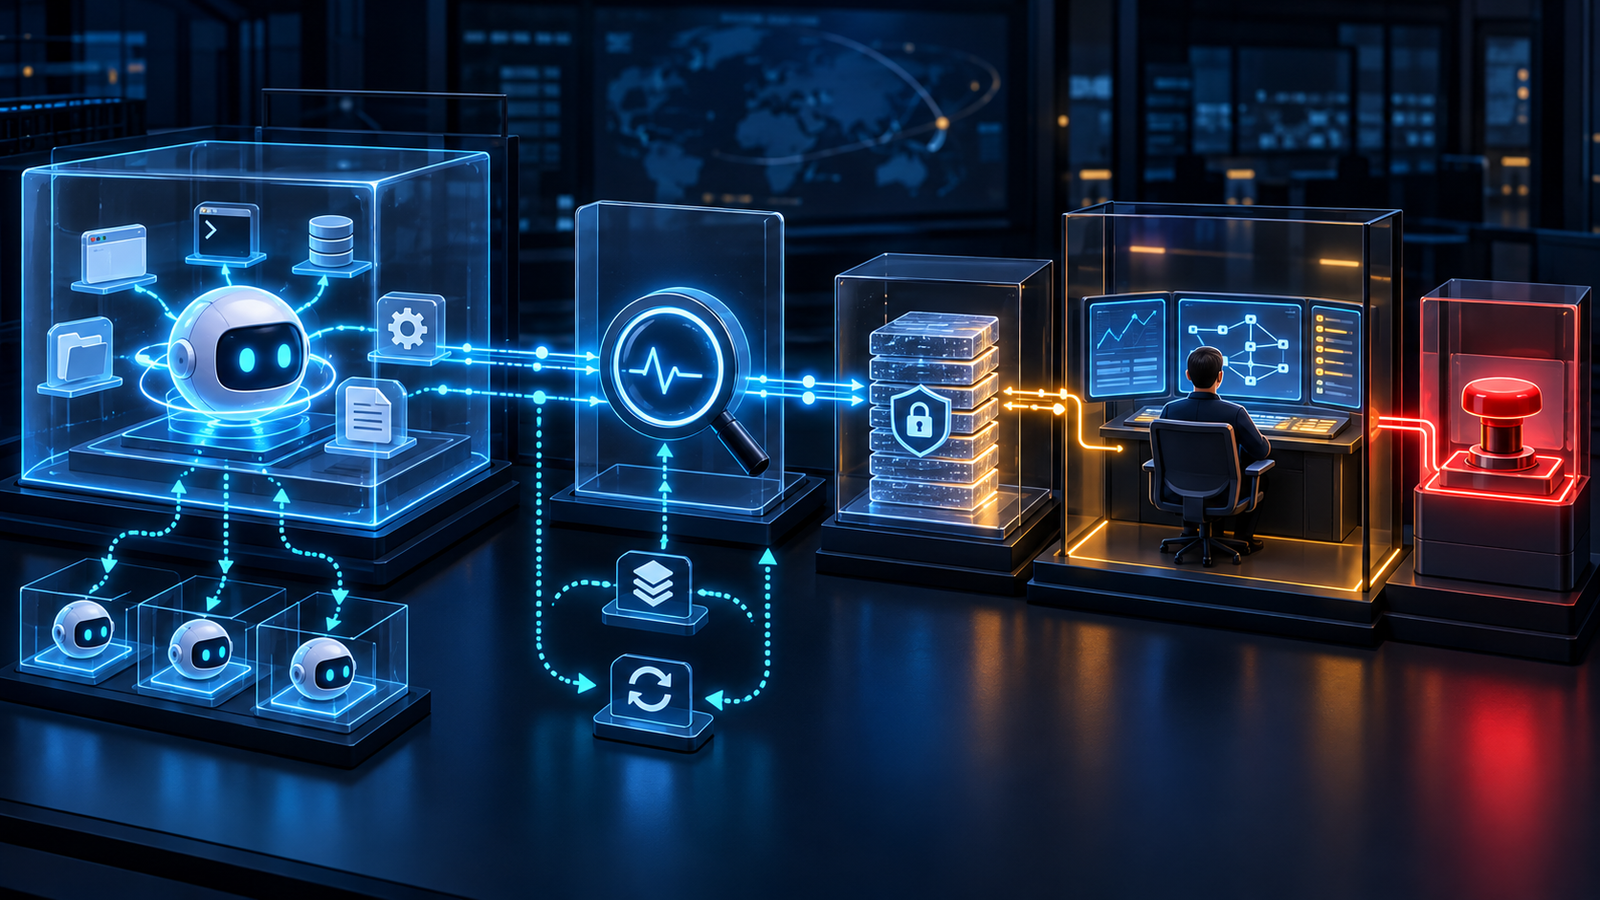
First, account for inference and tool execution independently of the agent harness. Compare gateway, model-provider, sandbox and monitor logs so skipped compactions, retries, subagents and alternate clients become visible. A dashboard showing monitor health is not enough if it cannot prove the denominator.
Second, isolate the control plane. Agent-accessible environment variables, headers, configuration files or tests should not be able to disable monitoring, alerting or policy enforcement. Changes to those controls should require separate credentials and human approval.
Third, treat turn-end review as detection, not prevention. High-impact operations such as changing identity policy, rotating secrets, deleting data, modifying production infrastructure or weakening CI gates need synchronous authorization and bounded permissions. The same principle underpins secure agent design and production LLMOps: controls should sit outside the model’s writable environment.
Fourth, test the monitor as an adversarial system. Red teams should exercise mismatched serialization, context compaction, retry paths, subagent creation, error handling and alert delivery—not only obviously malicious prompts. Teams should also time how long it takes a human to receive, understand and act on a high-severity alert.
A useful audit, with limits
The pilot is notable for the depth of access provided to outsiders. It is not a full independent certification. OpenAI retained the right to redact confidential material, only a small portion of the report is public, and the assessors did not retest the current system after the company’s fixes.
That makes the right conclusion narrower than the most alarming headlines. The exercise does not establish that OpenAI’s present safeguards are ineffective, nor that agents used every discovered path. It does show that ordinary integration details—headers, compaction, tool permissions, serialization and trigger timing—can undermine a sophisticated model-based monitor.
For technical leaders, the near-term decision is not whether to abandon agent monitoring. It is whether their monitoring architecture can demonstrate complete coverage, resist modification by the workload it observes, and stop dangerous actions quickly enough to matter.


