
OpenAI has moved its Decisions API into general availability, offering developers a specialized endpoint for low-latency classifications, risk scores and routing choices inside applications and AI-agent workflows.
NEW DELHI, 23 October 2026, 4:53 p.m. IST — OpenAI said on Thursday that its Decisions API is now generally available, positioning the service as a faster and cheaper way to make bounded choices than asking a general-purpose model to generate a full response.
The launch matters for platform and DevOps teams because many production agents spend much of their time on small control decisions: whether to retry, escalate, request clarification, send work for human review or stop an action. A dedicated decision layer could reduce latency and cost in those hot paths. It does not, however, remove the need for evaluation, deterministic policy checks or safe fallbacks when an answer is uncertain.
What OpenAI confirmed
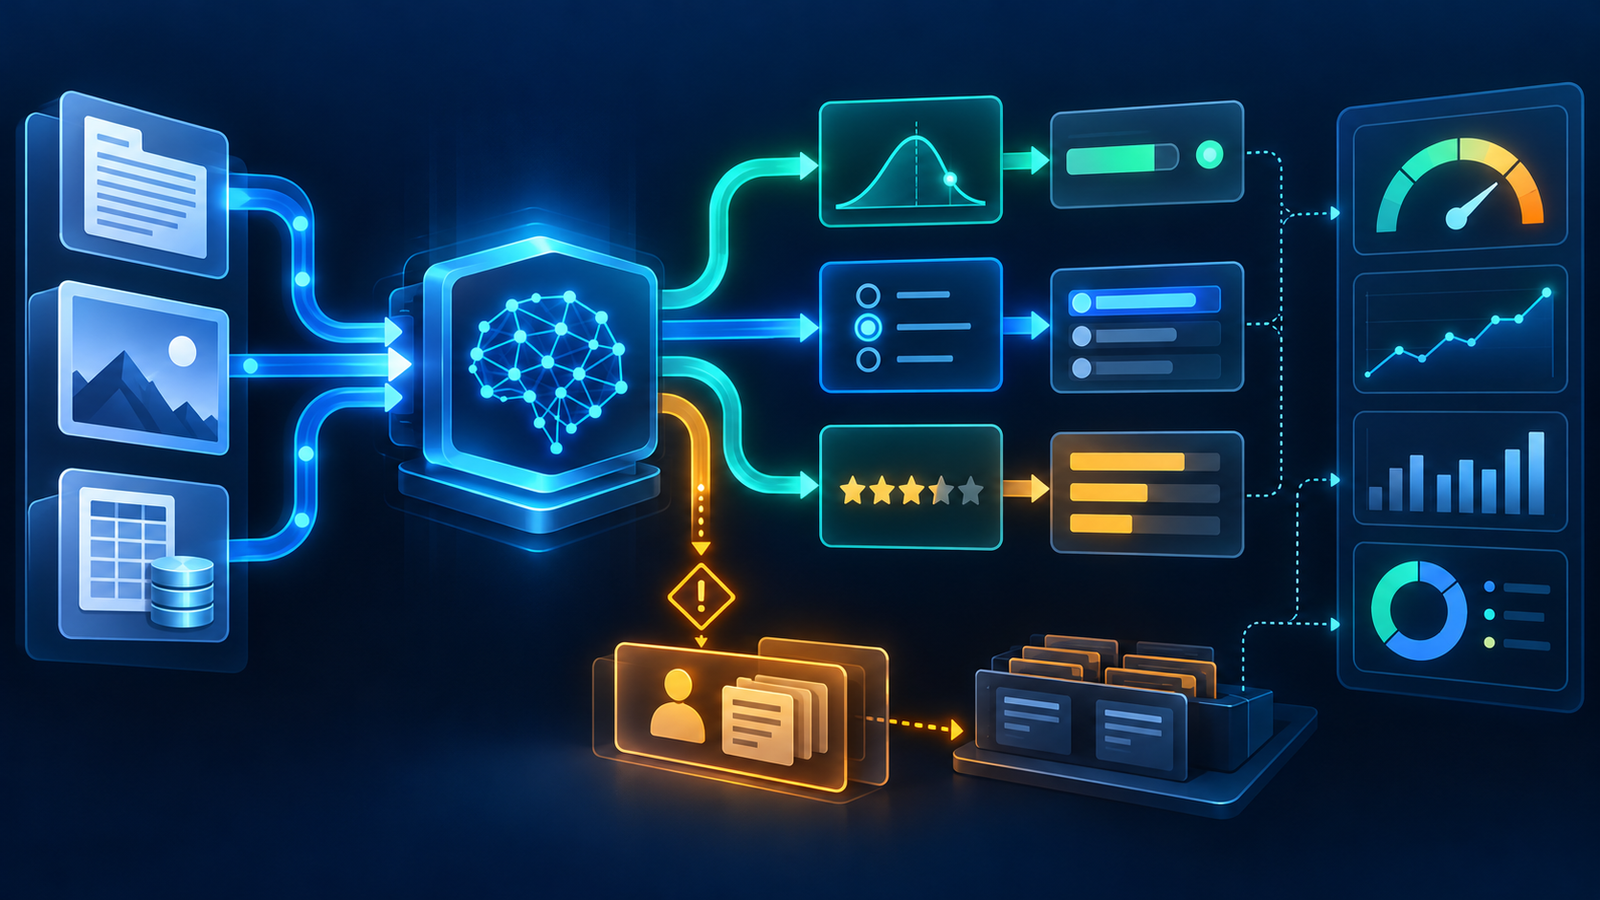
The OpenAI announcement says the API uses GPT-6 Luna and can process text, images and native JSON. Developers define a question and its allowed answers, and the service returns one of three typed results: a probability for a condition, a choice from a fixed set or a score against an ordered rubric.
OpenAI says the endpoint can answer as many as 400 questions in a single request, double the public-beta limit. General availability also adds prompt caching, images in question instructions, a native GPT-Live integration, data processing in the United States and Europe, and added capacity in several Asian regions.
The company claims the service can make decisions up to 10 times faster than GPT-6 Luna through the Responses API. That is a vendor comparison, not an independent benchmark, and actual latency will depend on region, input size, cache behavior and application networking.
OpenAI lists uncached input at $0.10 per million tokens and says there is no separate output-token charge. Its developer documentation notes that regional-processing premiums and long-context multipliers can still apply. Teams should model total request volume and cache behavior rather than extrapolating from the headline token rate alone.
Agent routing moves into the latency-sensitive path
OpenAI cited early customers using the API for document routing, AI-cost attribution, conversational orchestration and risk screening. Datadog said it tested the service to score the risk of agent-generated shell commands before autonomous remediation, reporting 40-times faster p95 latency than available frontier models at comparable accuracy. Box reported roughly five-times faster route selection across a 30-document evaluation, while Sierra reported sub-280-millisecond p95 latency in parts of its customer-service orchestration.
Those figures came from named customers in OpenAI’s launch material and were produced on different workloads, so they should not be compared with one another or treated as general performance guarantees. They do show why a bounded decision endpoint may be attractive: a routing gate can sit in the hot path without adding the delay and verbosity of a general answer-generation call.
The service is narrower by design. OpenAI’s documentation recommends the Responses API with Structured Outputs when an application needs a custom data object or written explanation, and function calling when a model needs to request a tool action with arguments. Decisions returns an assessment; the application remains responsible for what happens next.
Operational controls remain the hard part
For developers and SRE teams, the central design question is not whether a model can select an allowed answer. It is whether the surrounding system can detect when that answer should not be trusted.
Before putting the endpoint into a deployment gate, incident-response workflow or remediation loop, teams should build a labeled evaluation set from real traffic and select confidence thresholds based on the cost of false positives and false negatives. Low-confidence or high-impact decisions should fall back to a deterministic rule, a stronger model or a human reviewer. Changes to prompts, rubrics, thresholds and models should be versioned and promoted through the same review process as application code.
Observability should record the question version, model, latency, selected answer, confidence distribution, fallback taken and downstream outcome without retaining sensitive input unnecessarily. Existing LLMOps practices apply here: evaluation drift, regional latency, error rates and cost per successful workflow are more useful than request counts alone.
Security boundaries also need to stay outside the probabilistic service. A decision score should not be able to bypass identity controls, command allowlists, change windows or approval requirements. GravityDevOps’ guide to AI agent security explains why tool permissions, sandboxing and auditable execution remain necessary even when an agent appears confident.
What remains uncertain
OpenAI has not published a broad, independently reproducible benchmark covering the endpoint’s accuracy and latency across regions and workloads. The launch also does not establish universal confidence thresholds for safety-sensitive uses. Each implementation will need its own tests, because a useful cutoff for document classification may be unacceptable for production changes or security remediation.
The general-availability release nevertheless marks a practical shift in agent architecture. Instead of using one large model for planning, generation and every small routing choice, teams can split bounded decisions into a cheaper, faster service. The benefit will depend less on the demo response time than on whether engineers surround that service with measurements, policy enforcement and a reliable route to human judgment.
Sources
This report is based on OpenAI’s general-availability announcement, the Decisions API developer guide, the organization usage reference, and TechCrunch’s reporting on the release and decision-model market.


